Haddad Internal Tools
Designing one screen where operations teams create requests, catch missing data, and request the right assets — without switching tools.
Context
Haddad Brands manages high-volume internal workflows across production, digital content, photo studio, asset requests, and product tracking. A single request could involve multiple styles, missing product data, different asset needs, and several team handoffs.
The challenge was not just tracking work. It was helping teams understand which styles were valid, which ones needed correction, what assets were required, who owned the next step, and what could move forward.
Description
I designed internal workflow tools that turned dense production requests into clearer, validated workflows. The work focused on user requests, style management, bulk and individual style addition, missing data validation, asset requests, and status tracking.
The main UX challenge was handling operational complexity without making the interface feel heavier. I designed flows that separated valid styles from styles with missing information, surfaced errors inside the workflow, and kept asset actions close to the style they belonged to.
Instead of making teams inspect large tables manually or chase updates across channels, the system helped them see what was missing, what was ready, what was requested, and what needed attention next.
asset types
many styles
brand · color
all fields
category · color
confirmed
video · AI
One screen. Seven steps. From scattered request to validated, asset-ready work.
Read the full case study
The problem
The work was there. It was just hard to read.
Haddad's teams were handling production requests that had no structure. Styles, assets, and missing data were all mixed together. Nobody could tell at a glance what was ready to move and what wasn't.
This project was about fixing that. Not by adding more steps, but by making the existing work readable.
{{ card.title }}
{{ card.body }}
There was no way to tell, at a glance, what was ready to move.
Research and user testing
I watched how the team actually worked.
I sat with the team to see how requests really moved, then tested early designs with two people who do this work every day.
{{ m.label }}
{{ m.body }}
Tracking wasn't the problem. Knowing what was ready to move was.
One request could hold 40 styles. Some were fine. Some were missing a brand or a color. Some needed a specific type of photo. The old spreadsheet showed all of them the same way, so people had to check every row by hand.
Before: a row in a spreadsheet, with no owner and no status. After: a request with a clear status, a named owner, and the right actions right there.
Five questions I took into the interviews.
 RQ1
What makes a request "ready to move"?
Which fields, which checks, and who decides it's done?
 RQ2
Where does missing data hide?
Brand, category, color, size — and when does anyone notice?
 RQ3
How do assets actually get requested?
Flat PDP, on-model, video, AI — what happens beyond the default?
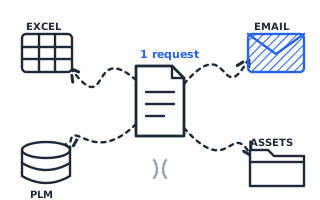 RQ4
How many tools does one request touch?
PLM, Excel, email, Get Assets — and why people switch between them.
 RQ5
What's still unmet?
What friction remains, even for operators who know the system well?
Pain points
These come from two interviews — with Joanna and Kathryn, who both handle production requests, but on different teams. Their problems were almost the same.
{{ f.n }}. {{ f.title }}
{{ f.body }}
Design direction
To make the problem sharper, I asked:
How might we let people see, at a glance, which styles are ready and which need attention — without leaving the screen?
Separate valid work from work that needs attention
Show ready and blocked styles in two distinct sections, always, so priority is obvious without scanning row by row.
Bring the whole request into one screen
Creating, validating, and requesting assets for a style should never require switching tools or re-entering information.
Seven steps, one screen. No jumping between tools.
The whole request — from the title to the asset request — happens in one place. Nothing lives in a separate email or spreadsheet.
Valid and invalid styles always show separately. You can't save until you've seen and fixed the errors.
Three directions, before picking one.
I looked at structure first, and worried about visuals later.
Three screens, sketched in one sitting.
Before opening Figma, I sketched the screens that mattered most: request creation, the valid/invalid split, and the asset request row.
{{ c.n }}. {{ c.title }}
{{ c.body }}
Four problems. Four things to fix.
{{ o.area }}
{{ o.problem }}
{{ o.opportunity }}
The experience, screen by screen
Every solution went through the same steps, tested with real requests.
Requests stopped getting lost.
Before, the important details lived in someone's head — name, owner, deadline, priority. Now they're captured when the request is made, and everyone can see them from that point on.
What each part of the screen does.
{{ z.label }}
{{ z.detail }}
The screen was structured around task progress: define the request, add styles, fix errors, confirm valid styles, and submit.
Errors show up as part of the work, not at the end.
Errors aren't a wall that stops you. They show up as part of the task, so you know what to fix before you save.
Requesting the right asset, from the same place.
Once styles were checked, people could request the assets they needed right from the style row — no switching tools, no copying references, no remembering where things were.
Every request at a glance — status, owner, and blockers.
Built to handle everything: clean requests, big batches with errors, partly done work, and overdue items — all readable without opening a single one.
Decisions and outcomes
Splitting valid from invalid styles removed the single biggest source of confusion found in testing.
Six decisions behind the design.
{{ d.title }}
{{ d.why }}
What this design set out to change.
These are the intentions behind the design, not measured results. They show what a structured, visible workflow is meant to do.
{{ o.body }}
What I learned
Two in-depth interviews surfaced sharper, more actionable findings than a wider, shallower survey would have.
It helped me read notes faster. It didn't make the decisions.
I used AI to sort through Joanna and Kathryn's interview notes and spot where their answers matched or differed. That was faster than reading both sets side by side by hand.
But every real decision — what to split, what to flag, what to cut from the step wizard — came from watching them actually use the tool, not from a summary.
A good internal tool doesn't just store work. It shows people what's ready, what needs attention, and what can move forward — without anyone sending a follow-up message. Splitting valid from invalid styles was the one change that made the rest of the screen work.
{{ r.title }}. {{ r.body }}
What I'd do with more time.
{{ l.body }}